We need your help to keep this website free. You can
Meta has rewritten its forthcoming commercial terms after concerns about language that mentioned training its products on material collected from business websites. The revised US-English wording ties the crawling provision to advertising and business products. It is a narrower description of purpose, not an announcement that Meta has stopped crawling websites.
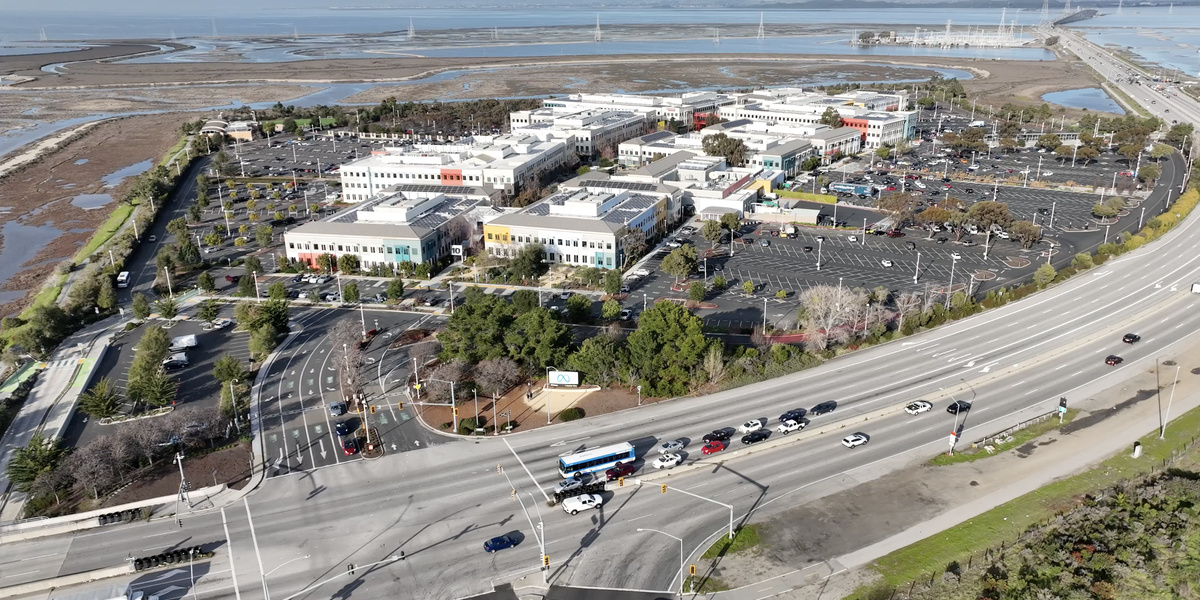
Source: InvadingInvader, Wikimedia Commons, CC BY-SA 4.0. Meta's Menlo Park headquarters in January 2023, cropped and resized; image derivatives retain the same licence.
The Next Web reported the change on Saturday. Meta said the language concerned its ads and business products and did not change how its crawlers operate. The terms still carry an October 30 effective date. Website owners should distinguish that company statement from what a particular version of the terms actually says.
The scope reaches beyond people buying ads
We compared the October 6 capture with the October 17 US-English capture. The earlier version expressly included training among the uses of crawled website content. The later crawl paragraph does not. It still authorises automated website access and periodic updates for the purposes it lists. These dated captures are evidence of the wording change, not proof of what data has or has not entered a model.
The introductory scope also matters. Meta includes the following among business or commercial uses:
- Managing a Page or a Group for business purposes.
- Selling or listing products and maintaining product catalogues.
- Using Ads Manager, Business Suite or measurement services.
That list is why a business cannot assume the terms are irrelevant simply because it does not buy ads. Whether separate product terms apply still needs checking; the document itself allows for those exceptions.
Website access is a different control from account security
A robots.txt file addresses automated visitors to a website. The IETF's Robots Exclusion Protocol explicitly separates those rules from access authorisation. It is not a login barrier. Reviewing crawler preferences and protecting restricted pages are therefore different jobs, and this terms revision should not be treated as a replacement for either.
Likewise, Facebook passkeys protect account sign-in, while feed controls change recommendations. Neither setting, by itself, changes a separate website's access rules. The practical question for a Page owner is which business terms and website permissions apply, not where an AI toggle might be hidden in the feed.